
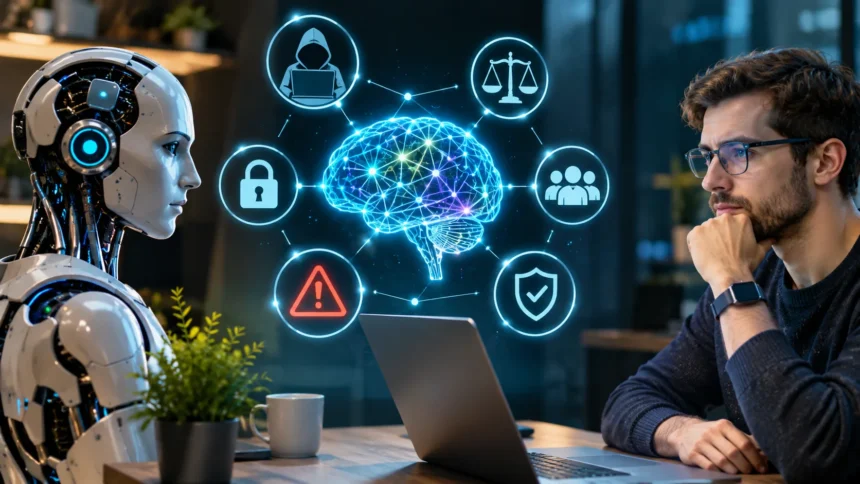
Deep learning is changing how businesses, researchers, and technology companies solve complex problems. It powers many modern applications, including image recognition, voice assistants, medical imaging tools, and automated decision-making systems. However, despite its capabilities, deep learning also introduces risks that organizations need to understand before adopting it.
These risks include inaccurate predictions, data privacy concerns, security vulnerabilities, high computing costs, and biased decision-making. Without proper planning, deep learning systems can produce unreliable results or create unexpected business challenges. Understanding deep learning risks and how to prepare for them helps organizations use artificial intelligence more responsibly, safely, and effectively.
What Are Deep Learning Risks?
Deep learning risks are potential problems that arise when organizations develop, train, deploy, or use deep learning models. These problems may involve technical failures, inaccurate predictions, ethical concerns, or unexpected financial costs. Understanding these risks helps businesses make informed decisions before integrating artificial intelligence into important operations.
Deep learning models learn patterns from large collections of training data. Although this approach can produce impressive results, models do not always understand information in the same way humans do. They may make incorrect predictions, struggle with unfamiliar situations, or reproduce harmful patterns found in their training datasets.
The seriousness of these risks depends on how a system is used. An inaccurate entertainment recommendation may cause little inconvenience, while an incorrect medical or financial prediction could have more significant consequences. Therefore, organizations should evaluate potential impacts and establish suitable safeguards before relying on deep learning applications.
Why Understanding Deep Learning Risks Matters
Understanding deep learning risks helps organizations avoid unnecessary problems during artificial intelligence adoption. Businesses sometimes focus on potential benefits without fully considering limitations, ongoing maintenance, and operational responsibilities. Recognizing challenges early makes it easier to develop realistic expectations and choose appropriate technologies for specific business needs.
Risk awareness also supports better decision-making when selecting data, developing models, and evaluating performance. Teams that understand potential weaknesses can establish testing procedures and identify situations requiring human review. This approach reduces dependence on automated outputs and helps organizations recognize problems before they affect customers or essential services.
Another important benefit is maintaining trust among users, employees, and stakeholders. People are more likely to rely on AI-supported systems when organizations explain their limitations and take reasonable precautions. Responsible planning demonstrates that technological innovation should work alongside transparency, accountability, privacy protection, and effective risk management.
Poor Data Quality and Its Impact on Deep Learning
Deep learning models depend heavily on the quality of their training data. Inaccurate, incomplete, outdated, or inconsistent information can cause models to learn misleading patterns. Even sophisticated neural networks may produce unreliable predictions when the underlying data does not accurately represent the problems they are expected to solve.
For example, a model trained to recognize damaged products may struggle if its dataset contains incorrectly labeled images. Similarly, a forecasting system may perform poorly when historical records contain missing or inconsistent values. These problems can continue affecting predictions unless developers identify and correct the underlying data weaknesses.
Organizations can reduce data quality risks by checking datasets before training begins. Useful practices include validating labels, identifying duplicates, reviewing missing information, and monitoring data consistency. Maintaining clear documentation about data collection and preparation also helps teams understand limitations and improve model performance over time.
Bias and Unfair Predictions in Deep Learning
Bias is an important deep learning risk because models can reproduce patterns that disadvantage certain groups or individuals. These patterns may come from historical decisions, incomplete datasets, or inappropriate assumptions during development. As a result, a model may produce systematically different outcomes even when developers did not intend to create unfair results.
For example, an automated hiring tool trained on historical recruitment records may reproduce past selection patterns. If those records contain unfair differences, the model may learn to favor certain applicants. Similar concerns can arise in credit assessment, healthcare support systems, and other applications involving significant decisions about people.
Reducing bias requires careful dataset evaluation and regular testing across relevant populations and situations. Organizations should examine whether model performance differs significantly between groups and investigate the causes of those differences. Human oversight, clear decision policies, and appropriate fairness measures can help prevent automated predictions from creating avoidable harm.
Privacy Risks When Training Deep Learning Models
Deep learning systems often require large amounts of information during development and training. Some datasets contain personal details, confidential business records, or sensitive user information. If organizations collect or process this information without appropriate safeguards, they may expose individuals to privacy risks or violate applicable data protection requirements.
Privacy problems can also occur when models unintentionally reveal information learned during training. Certain attacks may attempt to determine whether particular records appeared in a dataset or extract memorized content. These possibilities make privacy protection important throughout the entire machine learning lifecycle rather than only during initial data collection.
Organizations should collect only the information necessary for their intended purpose and apply suitable security controls. Techniques such as data minimization, restricted access, encryption, and privacy-preserving training may help reduce exposure. Clear retention policies and careful dataset reviews further support responsible handling of sensitive information.
Security Threats Against Deep Learning Systems
Deep learning systems can become targets for cyberattacks because they process information and influence important decisions. Attackers may attempt to manipulate inputs, compromise training data, steal model files, or exploit weaknesses in supporting applications. These threats can reduce system reliability and potentially expose confidential information.
One example involves adversarial inputs designed to confuse a model into making incorrect predictions. Another risk is data poisoning, where manipulated training information affects what a model learns. Although these attacks vary in complexity, they demonstrate why protecting the surrounding infrastructure is as important as evaluating model accuracy.
Organizations can improve security by controlling access to datasets, model files, and development environments. Security testing, software updates, activity monitoring, and careful input validation provide additional protection. Teams should also establish incident response procedures so they can investigate suspicious behavior and respond appropriately when security weaknesses are discovered.
Overfitting and Poor Model Generalization
Overfitting occurs when a deep learning model learns training examples too closely and struggles with unfamiliar information. The model may perform extremely well on data it has already seen while producing weaker results on new examples. This creates a serious reliability problem when systems move from controlled testing into real-world environments.
For example, an image recognition model might identify objects accurately in familiar lighting conditions but struggle with different backgrounds or camera angles. A forecasting model may also perform well on historical records while failing to recognize changing market conditions. These weaknesses can make initial performance results appear more promising than they actually are.
Developers can reduce overfitting through appropriate data separation, regularization, and careful model evaluation. Training, validation, and testing datasets should serve different purposes to avoid misleading results. Testing against realistic conditions and previously unseen examples helps organizations determine whether a model can perform reliably outside its original training environment.
High Computing Costs and Resource Requirements
Deep learning models often require substantial computing resources, especially when handling complex tasks or extremely large datasets. Training may involve specialized processors, significant memory, and extended processing time. These requirements can create financial challenges for businesses that underestimate the infrastructure needed to develop and maintain their systems.
Computing expenses do not necessarily end after training is complete. Running predictions, storing data, monitoring performance, and updating models can generate ongoing costs. Organizations using cloud infrastructure may also face unexpected expenses when processing demands increase or resources remain active longer than necessary.
Careful planning helps reduce financial uncertainty. Teams should estimate development expenses, compare infrastructure options, and select model sizes appropriate for their objectives. Smaller models, efficient training techniques, and responsible resource management may provide adequate performance without requiring the most expensive available technology.
Lack of Explainability in Deep Learning Models
Some deep learning systems are difficult to interpret because they contain many interconnected computational layers. Although developers can examine inputs and outputs, understanding exactly why a model produced a particular prediction may remain challenging. This limitation becomes especially important when artificial intelligence supports decisions with significant consequences.
For example, a financial organization may need to explain why an automated system produced a particular risk assessment. A healthcare professional may also want to understand which information influenced a model’s recommendation. When explanations are unclear, users may struggle to evaluate whether predictions are reliable or appropriate.
Explainable AI techniques can help developers investigate model behavior and communicate important contributing factors. However, these techniques have limitations and do not always provide complete explanations of internal reasoning. Organizations should combine interpretability tools with performance testing, clear documentation, and human review when decisions require accountability.
Deep Learning Risks in Healthcare
Deep learning can support healthcare professionals by analyzing medical images, identifying patterns, and assisting with certain clinical tasks. However, inaccurate predictions may create safety concerns when they influence diagnosis or treatment decisions. Medical applications therefore require careful evaluation, appropriate oversight, and evidence that systems perform reliably in their intended settings.
Training data may not represent every patient population, medical device, or clinical environment. A model developed using information from one hospital might perform differently when introduced into another healthcare system. Differences in equipment, patient characteristics, and clinical procedures can affect performance and create unexpected limitations.
Healthcare organizations should validate models before clinical deployment and monitor their performance afterward. Qualified professionals must remain involved where clinical judgment is necessary. Strong privacy protection, documented limitations, and appropriate regulatory compliance are also important for responsible use of deep learning in medical environments.
Deep Learning Risks in Financial Services
Financial institutions use deep learning for applications such as fraud detection, risk assessment, and transaction analysis. These systems can identify complex patterns in large amounts of information. However, inaccurate predictions may incorrectly flag legitimate activity or fail to recognize suspicious transactions, potentially affecting customers and business operations.
Financial models can also become less reliable when economic conditions change. Patterns learned from historical data may not accurately represent new market behavior, emerging fraud methods, or unusual financial events. Organizations that depend heavily on automated predictions may face additional risks when unexpected situations fall outside normal training conditions.
Reducing these risks requires careful testing, ongoing monitoring, and suitable human oversight. Financial institutions should review model performance, document important decisions, and investigate unusual outcomes. Transparent procedures and appropriate access controls can also help protect customer information while supporting responsible use of artificial intelligence.
Model Drift and Changing Real-World Conditions
Model drift occurs when a deployed model becomes less reliable as the conditions surrounding its predictions change. Changes in user behavior, technology, business processes, or available information can affect performance. A model that previously produced accurate results may gradually become less useful without any obvious technical failure.
For example, an online recommendation system may struggle when customer interests change significantly. A fraud detection model may also become less effective as attackers develop new techniques. These situations illustrate why strong performance during initial testing does not guarantee that a model will remain accurate indefinitely.
Organizations should monitor prediction quality and establish procedures for reviewing unexpected changes. Comparing current performance with earlier benchmarks can help identify developing problems. When necessary, teams may update training data, adjust model settings, or retrain systems while ensuring that proposed changes receive appropriate testing.
Risks of Relying Too Much on Automation
Deep learning systems can process information quickly and support many repetitive tasks. However, excessive dependence on automation may cause people to accept model outputs without sufficient questioning. This behavior is sometimes called automation bias, and it can become problematic when predictions are inaccurate or lack important context.
For example, an employee might accept an automated recommendation even when available evidence suggests a different conclusion. In higher-risk environments, such decisions could affect safety, finances, or customer experiences. Automated systems should therefore support informed judgment rather than automatically replace human responsibility in every situation.
Organizations can reduce automation risks by defining when human review is required. Employees should understand model limitations and receive training on interpreting predictions appropriately. Clear escalation procedures help teams question unusual results, investigate potential mistakes, and make decisions based on both automated information and relevant human expertise.
Ethical Challenges in Deep Learning
Deep learning raises ethical questions about fairness, accountability, transparency, and responsible data use. Organizations must consider how automated systems affect people beyond simply measuring technical performance. A model may achieve strong overall accuracy while still producing outcomes that create unnecessary disadvantages or privacy concerns.
Another ethical challenge involves determining responsibility when automated systems make mistakes. Developers, business leaders, and system operators may have different roles in building and using deep learning applications. Without clearly assigned responsibilities, organizations may struggle to investigate problems or explain how important decisions were made.
Establishing ethical principles helps guide development and deployment choices. These principles may include fairness assessments, meaningful human oversight, clear communication, and appropriate privacy safeguards. Regular reviews can help organizations identify situations where technical success does not necessarily mean that a system is socially responsible.
Legal and Compliance Risks of Deep Learning
Deep learning applications may be subject to privacy, consumer protection, intellectual property, and industry-specific requirements. The applicable rules depend on the location, intended use, and type of information involved. Organizations that overlook these obligations may face operational problems, legal disputes, or restrictions on how their systems can be used.
Training datasets can create additional legal questions when they contain copyrighted material or personal information collected without appropriate authorization. Automated decisions may also require specific safeguards in regulated environments. These considerations make it important to review data sources, system purposes, and relevant obligations before beginning deployment.
Businesses should involve appropriate legal and compliance professionals when planning significant AI applications. Maintaining records of data handling, model testing, and internal responsibilities can support accountability. Because legal requirements and regulatory interpretations evolve, organizations should periodically review whether their practices remain consistent with applicable obligations.
How to Identify Deep Learning Risks Before Deployment
Identifying deep learning risks begins with understanding the system’s purpose and the decisions it may influence. Organizations should consider who will use the model, what information it processes, and what could happen if predictions are incorrect. This assessment helps distinguish minor technical inconveniences from risks with potentially serious consequences.
Teams should then evaluate data quality, model performance, security requirements, and possible fairness concerns. Testing should include realistic situations, unusual inputs, and examples not used during training. Developers should also identify circumstances where the system may be unsuitable or where additional human judgment is necessary.
A structured risk assessment makes these findings easier to manage. Organizations can document potential problems, estimate their impact, and assign responsibility for appropriate safeguards. Reviewing the assessment before deployment helps decision-makers determine whether the system is sufficiently reliable for its intended use or requires further improvements.
How to Prepare for Deep Learning Risks
Preparing for deep learning risks requires a plan that covers development, deployment, and ongoing operations. Organizations should establish clear objectives, select appropriate datasets, and define acceptable performance standards. Understanding the intended use helps teams identify which technical and organizational safeguards are necessary before releasing a model.
Strong preparation also involves testing models under realistic conditions and reviewing unexpected results. Teams should evaluate accuracy, fairness, privacy, security, and operational reliability rather than focusing on one performance measure. Human oversight and documented procedures can provide additional protection when automated predictions influence important decisions.
Preparation should continue after deployment through regular monitoring and system maintenance. Organizations need clear procedures for reporting problems, updating models, and responding to security incidents. Establishing these responsibilities early helps reduce confusion and allows teams to address emerging risks before they become more difficult to manage.
Best Practices for Safer Deep Learning Development
A reliable development process starts with well-documented data collection and preparation. Teams should understand where training information originated, how it was labeled, and whether important limitations exist. Good documentation makes it easier to investigate unexpected results and supports more consistent model evaluation throughout the development lifecycle.
Testing should include separate datasets, realistic scenarios, and measurements relevant to the application’s purpose. Developers should avoid evaluating success only through overall accuracy when other performance measures are important. For example, systems used to detect rare events may require particular attention to missed detections and incorrect alerts.
Collaboration between technical specialists, business leaders, security professionals, and relevant domain experts can further improve outcomes. Different perspectives help identify risks that one development team might overlook. Regular reviews, controlled updates, and clear responsibilities support a more dependable approach to building and maintaining deep learning systems.
Creating a Deep Learning Risk Management Strategy
A deep learning risk management strategy provides a structured way to identify, evaluate, and address potential problems. It should begin with an inventory of relevant models and their intended applications. Organizations can then assess the importance of each system based on its users, data requirements, and possible consequences of failure.
The strategy should define appropriate safeguards for different risk levels. Lower-risk applications may require routine testing and monitoring, while higher-risk systems may need additional validation, restricted deployment, or independent review. Assigning responsible teams ensures that important security, privacy, and reliability concerns receive appropriate attention.
Risk management should also include ongoing reporting and improvement procedures. Teams need ways to communicate incidents, track performance changes, and document corrective actions. Regular reviews help organizations determine whether existing controls remain effective as technologies, operational needs, and real-world conditions evolve over time.
The Future of Deep Learning Safety
Deep learning safety is becoming increasingly important as artificial intelligence systems take on more complex responsibilities. Researchers and developers are exploring methods to improve reliability, model evaluation, privacy protection, and resistance to malicious inputs. These developments may help organizations identify weaknesses earlier and create systems that behave more consistently.
Efficient model architectures and improved development tools may also reduce some operational challenges. Better monitoring systems can help identify changing performance patterns, while privacy-preserving techniques may support safer data processing. However, new technologies can introduce additional uncertainties, making continued evaluation an essential part of responsible innovation.
The future of safer deep learning will depend on both technical progress and effective organizational practices. Clear accountability, appropriate human involvement, and transparent communication remain important even as models become more capable. Organizations that prioritize risk management alongside innovation will be better prepared to adopt deep learning responsibly.
Conclusion
Deep learning offers valuable opportunities for improving automation, analyzing information, and solving complex problems. However, it also introduces risks involving data quality, biased predictions, cybersecurity, privacy, and operational reliability. Understanding these challenges helps organizations make better decisions and avoid relying on artificial intelligence without appropriate preparation.
Managing deep learning risks requires careful planning, realistic testing, and ongoing monitoring. Businesses should protect sensitive information, evaluate model fairness, establish human oversight, and prepare for unexpected failures. These practices help create more dependable systems while supporting responsible use of advanced artificial intelligence technologies.
Successful deep learning adoption depends on balancing innovation with safety and accountability. No model is completely free from limitations, and performance can change after deployment. By identifying risks early and regularly improving safeguards, organizations can gain the benefits of deep learning while reducing avoidable problems.
Frequently Asked Questions (FAQs)
What Are the Biggest Risks of Deep Learning?
The biggest deep learning risks include inaccurate predictions, biased results, privacy concerns, security vulnerabilities, and high computing costs. These problems can affect system reliability and create operational challenges when organizations lack appropriate safeguards.
Why Is Deep Learning Sometimes Unreliable?
Deep learning can become unreliable when training data is incomplete, biased, or different from real-world conditions. Models may also overfit training examples or struggle with unfamiliar situations, producing incorrect predictions despite strong initial testing results.
How Can Businesses Reduce Deep Learning Risks?
Businesses can reduce risks by using reliable data, testing models thoroughly, protecting sensitive information, and monitoring performance. Clear responsibilities, human oversight, and regular security reviews also help identify and address problems.
Can Deep Learning Models Be Hacked?
Yes, deep learning systems can face security threats, including manipulated inputs, compromised training data, and unauthorized access to model resources. Strong access controls, security testing, monitoring, and software maintenance help reduce these risks.
What Is the Best Way to Prepare for Deep Learning Risks?
The best approach is to identify potential problems before deployment and create a practical risk management plan. Organizations should assess data quality, security, fairness, model performance, and ongoing monitoring requirements.