
Machine learning is changing how businesses analyze information, predict outcomes, and automate everyday tasks. From healthcare and banking to online shopping and cybersecurity, intelligent systems can improve efficiency and support better decisions. However, these benefits also come with potential problems that organizations need to understand before adopting the technology.
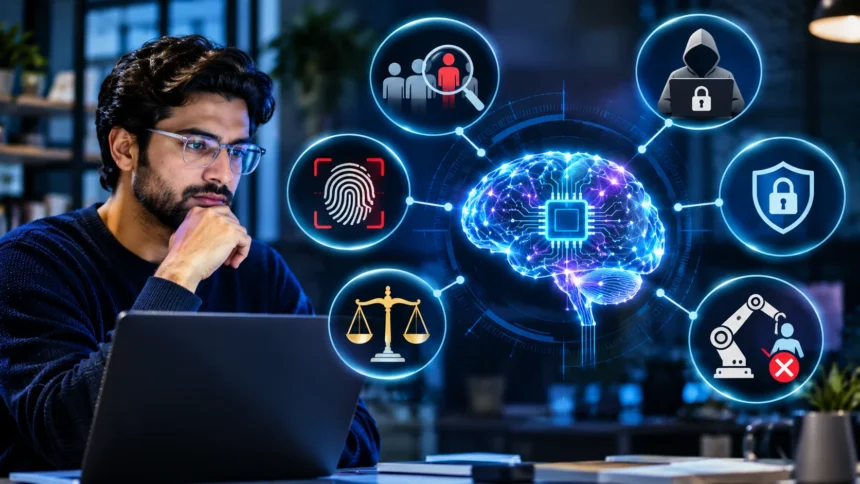
Machine learning risks include inaccurate predictions, data privacy concerns, algorithmic bias, security vulnerabilities, and unexpected operational failures. Without proper planning, these problems can affect users, increase costs, and damage business trust. Understanding the risks of machine learning helps organizations develop responsible AI systems while maintaining reliable performance and appropriate human oversight.
What Are Machine Learning Risks?
Machine learning risks are potential problems that arise when algorithms analyze data, make predictions, or influence decisions. These risks can affect accuracy, privacy, fairness, security, and business operations. Although machine learning models can identify complex patterns, they are not automatically reliable in every situation. Their performance depends on training data, model design, and real-world conditions.
One major concern is that machine learning systems can produce convincing results even when their predictions are incorrect. For example, a financial forecasting model may recommend unsuitable decisions after learning from incomplete historical information. If employees trust those outputs without checking them, small errors can become larger business problems. Understanding model limitations is therefore essential.
Organizations can reduce these risks by setting clear expectations before developing or purchasing machine learning tools. Teams should identify possible failures, evaluate their consequences, and establish appropriate safety measures. Regular testing and monitoring also help detect weaknesses early. Responsible implementation focuses on balancing automation benefits with accuracy, transparency, and meaningful human control.
Poor Data Quality and Inaccurate Predictions
Poor data quality is one of the most significant machine learning risks because algorithms depend on the information used during training. Missing values, outdated records, duplicate entries, and incorrect labels can all reduce prediction quality. Even a sophisticated model may produce unreliable results when important details are inaccurate. Large datasets cannot automatically compensate for serious information problems.
For example, a retail business might train a demand forecasting model using sales records that contain missing transactions. The model could underestimate product demand and recommend insufficient inventory for upcoming periods. Similar problems may affect medical analysis, transportation planning, and customer behavior predictions. In each situation, inaccurate information can lead to costly or inconvenient decisions.
Improving data quality requires consistent collection methods, validation procedures, and routine reviews of training datasets. Teams should investigate missing values, check unusual records, and maintain clear documentation about information sources. Automated checks can identify errors before they enter the model development process. Reliable data preparation makes predictions more useful and reduces preventable mistakes.
Data Privacy and Confidential Information
Machine learning systems often process personal or confidential information, creating important privacy concerns for businesses and individuals. Training datasets may contain customer details, financial information, medical records, or internal company documents. If this information is collected or shared without appropriate safeguards, people may experience unwanted exposure. Privacy risks can also damage organizational credibility.
Another concern involves models unintentionally revealing information associated with their training data. Certain systems may memorize sensitive details or expose information through poorly protected interfaces. Combining multiple datasets can sometimes make individuals identifiable even when direct identifiers have been removed. These possibilities make privacy protection important throughout the machine learning lifecycle.
Organizations should collect only the information needed for a clearly defined purpose and restrict access to authorized users. Encryption, appropriate data retention rules, and privacy impact assessments can reduce unnecessary exposure. Techniques such as differential privacy may provide additional protection in suitable applications. Clear handling procedures also help organizations respect applicable data protection requirements.
Security Threats and Cyberattacks
Machine learning introduces security risks because attackers may target both the information used to train models and the systems that deliver predictions. Traditional cybersecurity measures remain important, but intelligent applications can create additional weaknesses. Poorly secured model interfaces, databases, or development pipelines may expose valuable information. Organizations must consider these threats before deploying models into production.
One example is data poisoning, where an attacker attempts to influence model behavior by manipulating training information. Another is an adversarial attack, which uses specially constructed inputs to encourage incorrect predictions. These methods can affect applications such as image recognition or automated threat detection. Their success depends on the system and the attacker’s level of access.
Reducing security risks requires strong access controls, protected development environments, and careful validation of training data. Security teams should test models against realistic threats and monitor unusual activity after deployment. Keeping software dependencies updated also helps address known vulnerabilities. Effective protection combines machine learning security practices with established organizational cybersecurity procedures.
Algorithmic Bias and Unfair Decisions
Algorithmic bias occurs when machine learning systems produce systematically unfair outcomes for certain people or groups. These problems may originate from unrepresentative datasets, historical inequalities, or unsuitable modeling assumptions. A model can reproduce patterns found in its training information without understanding their social consequences. This makes fairness an important concern in automated decision-making.
For example, a hiring model trained on historical recruitment records might favor applicants who resemble previously selected candidates. If those records reflect unequal opportunities, the model may reinforce existing disadvantages. Similar concerns can arise in lending, insurance, education, and other consequential applications. High overall prediction accuracy does not guarantee fair treatment across different groups.
Organizations should examine training data for gaps and compare model performance across relevant populations. Fairness assessments can reveal differences that average performance measurements might hide. Developers should also involve domain experts and affected stakeholders when defining acceptable outcomes. Human review and accessible appeal processes provide additional protection when automated decisions affect people’s opportunities.
Overfitting and Poor Model Generalization
Overfitting happens when a machine learning model learns the training data too closely instead of identifying patterns that apply to new situations. Such a model may achieve impressive training accuracy but perform poorly when given unfamiliar examples. This problem often occurs when the model is unnecessarily complex. Limited or noisy datasets can increase the risk.
Underfitting creates a different challenge because the model fails to learn important relationships even within the available training information. Both problems reduce prediction reliability and can make performance measurements misleading. For example, an overly simple sales forecasting model may overlook seasonal demand patterns. An overfitted model might instead react too strongly to random historical changes.
Developers can address these problems through suitable model selection, cross-validation, regularization, and careful feature engineering. Comparing training results with validation performance helps reveal weaknesses before deployment. A separate test dataset should provide an additional check on generalization. Choosing appropriate model complexity is often more valuable than automatically selecting the most advanced algorithm.
Lack of Transparency and Explainability
Some machine learning systems are difficult to interpret because their predictions depend on complicated relationships among numerous variables. This creates what is often called the black-box problem. Users may receive an output without clearly understanding which factors influenced it. Limited transparency becomes particularly concerning when decisions affect healthcare, employment, financial services, or personal opportunities.
Imagine a lending system that identifies an application as high risk without providing an understandable explanation. The applicant may struggle to determine which information influenced the assessment or whether a mistake occurred. Employees may also find it difficult to investigate questionable decisions. These challenges can reduce trust and make accountability harder to establish.
Organizations can improve explainability by selecting interpretable algorithms when they meet the application’s requirements. Feature importance analysis and explanation tools can provide useful insights into more complex models. However, these explanations may simplify the underlying process and should not be treated as perfect descriptions. Clear documentation and human review remain important for responsible decisions.
Model Drift and Changing Real-World Conditions
Machine learning models learn from patterns that exist in their training data, but those patterns do not always remain stable. Customer behavior, market conditions, technology, and environmental factors may change over time. When a model becomes less reliable because circumstances have shifted, organizations may experience model drift. This can gradually reduce prediction accuracy without obvious technical failures.
For example, an inventory forecasting system might learn purchasing patterns from several years of stable consumer demand. A sudden economic change or major product trend could make those patterns less useful. The model may continue producing predictions based on outdated relationships. Without regular performance reviews, businesses might not recognize the problem until its consequences become noticeable.
Continuous monitoring helps organizations identify changes in incoming data and model performance. Teams should establish meaningful performance indicators and investigate unusual trends before making adjustments. Retraining with recent, validated information may improve results when the underlying problem has changed. However, updates should be tested carefully because newer models are not automatically more accurate.
Excessive Automation and Reduced Human Oversight
Automation can improve efficiency, but excessive reliance on machine learning creates risks when people accept predictions without evaluating them. This behavior is often called automation bias. Employees may assume that algorithmic recommendations are objective or consistently accurate. Such assumptions become dangerous when models encounter unusual circumstances or make mistakes that require experienced human judgment.
For example, an automated customer service system might provide incorrect information about a complicated billing issue. If employees follow its recommendation without checking account details, the customer could receive an unsuitable resolution. Similar problems may arise in medical triage or financial analysis. Automation should support human decision-making rather than eliminate necessary professional responsibility.
Organizations can reduce these risks by defining which decisions require human review and when automated recommendations should be questioned. Employees need practical training about model limitations and common failure patterns. Escalation procedures should make it easy to investigate uncertain results. Effective human oversight ensures that responsibility remains clear even when routine tasks become automated.
Legal, Ethical, and Regulatory Risks
Machine learning applications may involve legal requirements concerning privacy, discrimination, consumer protection, intellectual property, and automated decisions. These obligations differ between countries, industries, and particular uses of technology. Organizations that overlook applicable requirements may face penalties, disputes, or operational restrictions. Compliance planning should therefore begin before sensitive systems are developed or introduced.
Ethical concerns can also arise even when an application technically follows existing laws. A recommendation system might exploit behavioral patterns in ways that undermine informed user choices. Another model could make important decisions without providing meaningful explanations or opportunities for review. Responsible development requires considering potential consequences for people, not simply measuring business efficiency.
Organizations should establish clear governance policies covering data collection, model evaluation, accountability, and acceptable uses. Legal specialists and relevant domain experts can help identify requirements before deployment. Documentation should explain how decisions are made, reviewed, and corrected when problems occur. Regular assessments help organizations respond to changing regulations and emerging ethical concerns.
High Costs and Operational Failures
Machine learning development can involve significant expenses for data preparation, computing infrastructure, specialized personnel, and ongoing maintenance. Complex models may require powerful hardware and extensive training time. These demands can make projects difficult for organizations with limited resources. High technical performance does not necessarily justify the investment when simpler solutions could achieve similar results.
Operational problems may also appear when models are connected to existing business software. Data pipelines can fail, prediction services may become unavailable, and unexpected input formats can disrupt processing. A model that works well in a testing environment may struggle with real production workloads. These failures can affect customer experiences and important internal operations.
Organizations should compare potential benefits with development and maintenance costs before committing to a project. Starting with a simple baseline helps determine whether advanced machine learning is genuinely necessary. Automated testing, backup procedures, and reliable system monitoring can reduce operational interruptions. Regular cost reviews also help prevent infrastructure spending from exceeding practical business value.
How to Reduce Machine Learning Risks
Managing machine learning risks begins with identifying how a system could fail and who might be affected. Teams should evaluate the likelihood and potential consequences of each problem before deployment. High-impact applications require stronger safeguards than tools used for minor administrative tasks. A structured risk assessment helps organizations focus resources where protection matters most.
Testing should cover prediction accuracy, data quality, fairness, privacy, security, and performance under unusual conditions. Developers need representative evaluation datasets and clear criteria for acceptable results. Documentation should explain model limitations and identify situations that require additional review. These practices help organizations identify weaknesses before users depend on the system.
Risk management must continue after a model enters production because data, users, and business requirements can change. Organizations should monitor performance, investigate incidents, and maintain clear responsibilities for correcting problems. Employees also need appropriate training and reliable reporting channels. Combining technical safeguards with effective governance makes machine learning systems more dependable and accountable.
Conclusion
Machine learning risks are important considerations for organizations adopting artificial intelligence and automated decision-making. Problems involving poor data quality, algorithmic bias, privacy, security, and unreliable predictions can affect both businesses and individuals. These challenges do not mean machine learning should be avoided entirely. Instead, they highlight the need for careful design, appropriate safeguards, and realistic expectations.
Responsible machine learning requires more than accurate algorithms and powerful computing systems. Organizations should maintain reliable datasets, evaluate fairness, protect sensitive information, and monitor models after deployment. Human oversight is particularly important when automated recommendations influence consequential decisions. A well-managed approach helps reduce preventable errors while preserving the practical benefits of intelligent technology.
The safest way to adopt machine learning is to begin with clear objectives and understand the potential consequences of failure. Regular testing, transparent processes, and continuous improvement help maintain trust as systems evolve. No model can eliminate every possible risk. However, thoughtful planning and accountable management can make machine learning more reliable, useful, and responsible.
FAQs
What are the biggest risks of machine learning?
The biggest machine learning risks include inaccurate predictions, poor data quality, algorithmic bias, privacy violations, security vulnerabilities, and model drift. These problems can affect user trust, business performance, and important decisions.
How can businesses reduce machine learning risks?
Businesses can reduce risks through reliable data preparation, model testing, security safeguards, fairness evaluations, and continuous monitoring. Human oversight and clear accountability procedures also help prevent automated errors from causing serious consequences.
Why is machine learning bias dangerous?
Machine learning bias can produce unfair or inaccurate outcomes for certain individuals or groups. It becomes especially concerning when algorithms influence employment, financial services, healthcare, or other decisions that affect people’s lives.
Can machine learning systems be hacked?
Yes, machine learning systems can face cyberattacks targeting their training data, model interfaces, or supporting infrastructure. Access controls, security testing, protected data pipelines, and regular monitoring help reduce these threats.
Is machine learning safe for businesses?
Machine learning can be useful and reasonably safe when organizations apply appropriate controls. Its safety depends on the application, data quality, security measures, performance testing, and the level of human oversight involved.